Authors: Immanuel Abdi, Akshat Gupta, Micah Mok, Alexander Lu, Nicholas Lee, Gopala Anumanchipalli
Paper: https://arxiv.org/abs/2601.20861
Code: https://github.com/akshat57/es-catastrophic
Model: https://huggingface.co/collections/immanuelabdi/es-at-scale-lead-to-catastrophic-forgetting
TL;DR
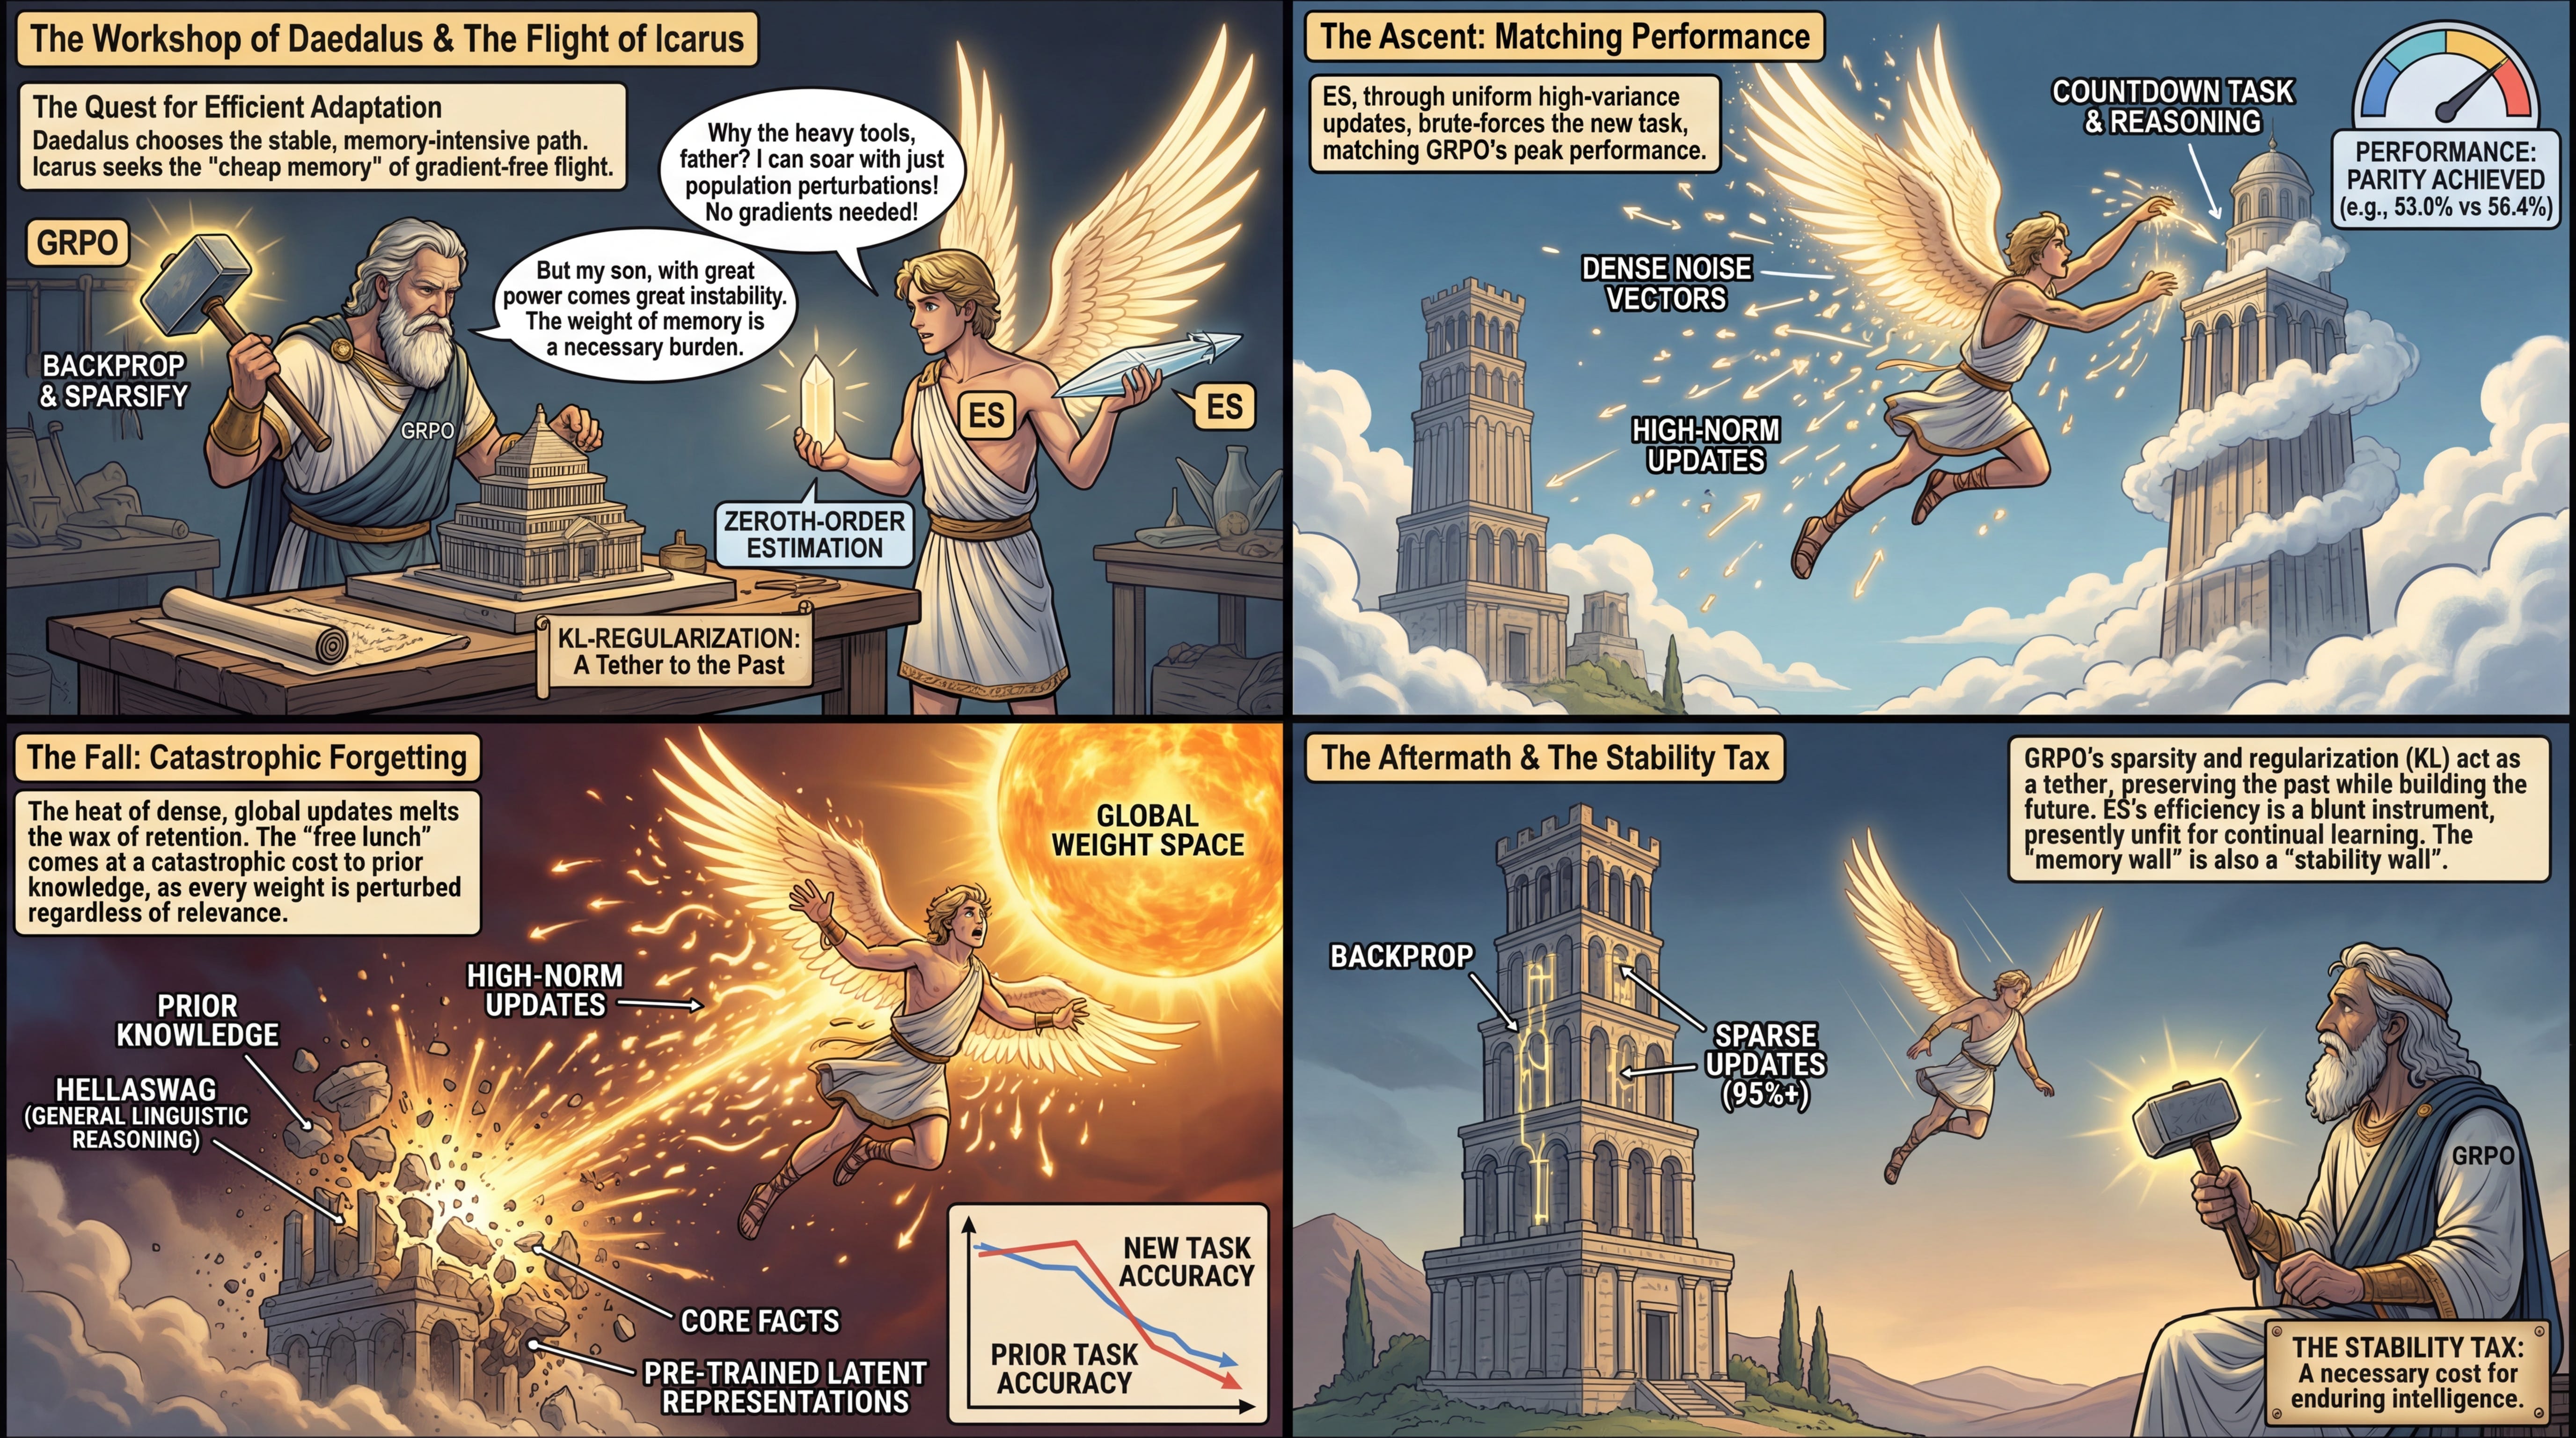
WHAT was done? The authors conducted a rigorous empirical analysis of Evolutionary Strategies (ES) for fine-tuning Large Language Models (LLMs), specifically comparing it against Group Relative Policy Optimization (GRPO). While verifying that ES can match gradient-based methods on specific reasoning tasks, they demonstrate that ES induces severe catastrophic forgetting of prior knowledge.
WHY it matters? As the field pushes toward on-device learning and continuous adaptation, memory-efficient, gradient-free methods like ES are becoming attractive alternatives to backpropagation. However, this study reveals a critical failure mode: ES achieves performance through dense, high-norm parameter updates that globally disrupt the model, suggesting it is currently unsuitable for continual learning scenarios despite its hardware efficiency.
Details
The Gradient Bottleneck vs. The Evolutionary Promise
The central conflict in deploying continually learning AI systems is the memory wall imposed by backpropagation. Standard adaptation methods like SFT or RLHF require the storage of gradients, optimizer states, and intermediate activations, which imposes a massive overhead during training. This has led to a resurgence of interest in Evolutionary Strategies (ES), particularly following recent work by Qiu et al. (2025) [review, but see also another paper review] which positioned ES as a viable, memory-efficient competitor to reinforcement learning techniques like GRPO (Group Relative Policy Optimization).
The theoretical appeal is clear: if we can estimate updates via population-level perturbations rather than explicit gradient calculation, we can fine-tune models on consumer hardware or at the edge. However, the authors of this paper identify a critical oversight in previous literature. While ES can optimize a specific metric (e.g., solving a math problem), previous studies failed to analyze the collateral damage. This paper investigates whether the “free lunch” of gradient-free optimization comes at the cost of the model’s general capabilities, framing the problem not just as one of convergence, but of retention.
