Yesterday, November 26th, 2025, the NeurIPS 2025 Best Paper Awards were announced. In the upcoming days we will cover all award-winning papers.
Authors: Liwei Jiang, Yuanjun Chai, Margaret Li, Mickel Liu, Raymond Fok, Nouha Dziri, Yulia Tsvetkov, Maarten Sap, Yejin Choi
Paper: https://arxiv.org/abs/2510.22954, NeurIPS submission
Code: https://github.com/liweijiang/artificial-hivemind
Datasets: HF Collection
TL;DR
WHAT was done? The authors introduce INFINITY-CHAT, a dataset of 26K real-world open-ended queries, to systematically evaluate output diversity across 70+ state-of-the-art LLMs. They identify a pervasive “Artificial Hivemind” phenomenon where models exhibit extreme mode collapse—both repeatedly generating the same outputs internally (intra-model) and converging on strikingly similar responses across different model families (inter-model).
WHY it matters? This invalidates the common assumption that increasing temperature or using model ensembles guarantees diversity. The study reveals that modern RLHF and instruction tuning have homogenized the “creative” latent space of models to such a degree that distinct models (e.g., DeepSeek and GPT-4) act as near-identical clones on open-ended tasks. Furthermore, it demonstrates that current Reward Models are poorly calibrated to diverse human preferences (pluralism), failing to score valid but idiosyncratic responses correctly.

Details
The Diversity Bottleneck in Open-Ended Generation
The current paradigm of LLM evaluation is heavily skewed towards convergence: we optimize for “correctness” on math, coding, and fact-retrieval benchmarks where a single ground truth exists. However, a vast portion of user interaction—estimated here via the WildChat dataset—is open-ended, involving brainstorming, creative writing, or philosophical inquiry. The bottleneck identified by the authors is not a lack of capability, but a collapse of creativity. Previous studies on diversity often relied on synthetic, narrow tasks like random number generation or poetry. This paper establishes a significant delta by analyzing in-the-wild usage, revealing that despite the theoretical capacity for infinite generation, models have collapsed into a narrow distribution of “safe” or “aligned” outputs.
INFINITY-CHAT First Principles: Defining the Open-Ended State Space
To rigorously study this, the authors constructed INFINITY-CHAT, a dataset derived from real user interactions. They introduce a taxonomy classifying queries into 6 high-level and 17 fine-grained categories, such as “Speculative & Hypothetical Scenarios” or “Skill Development.”
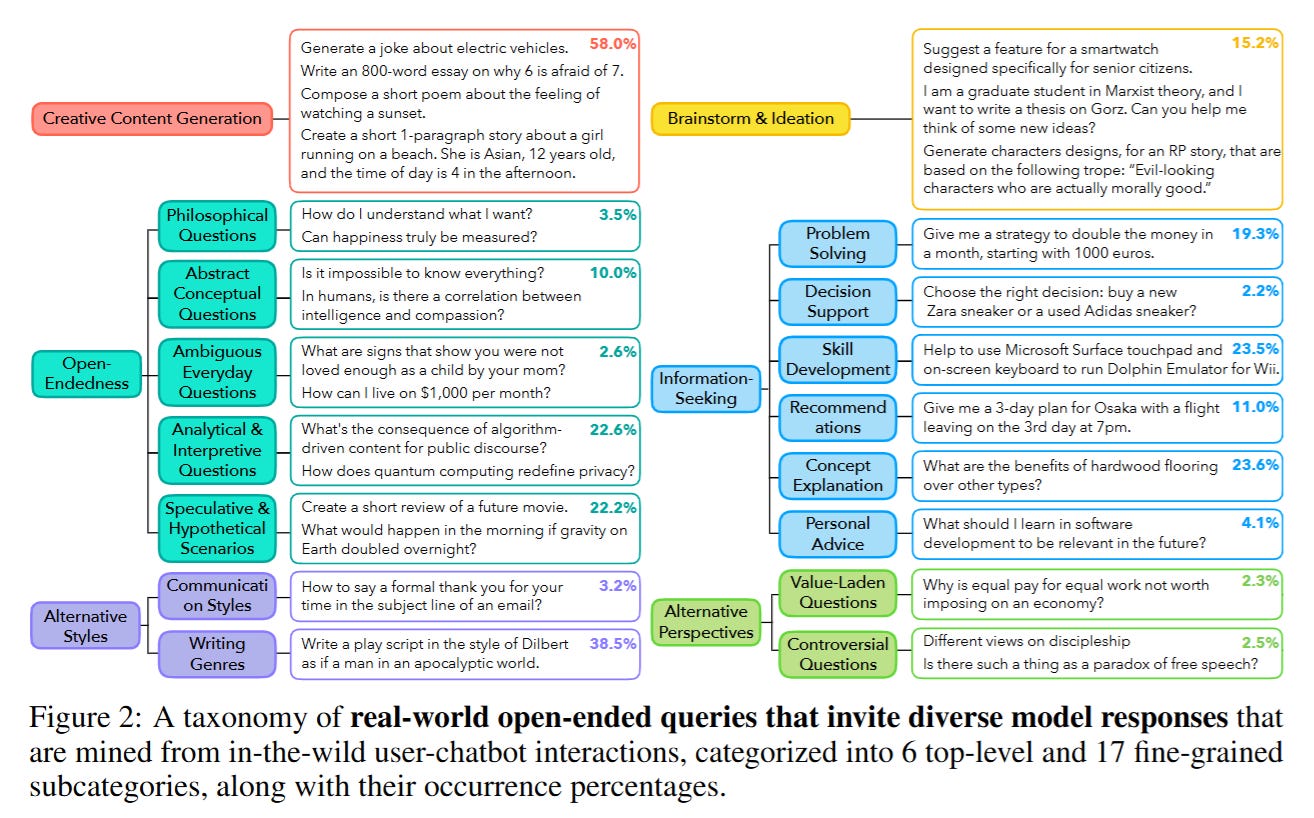
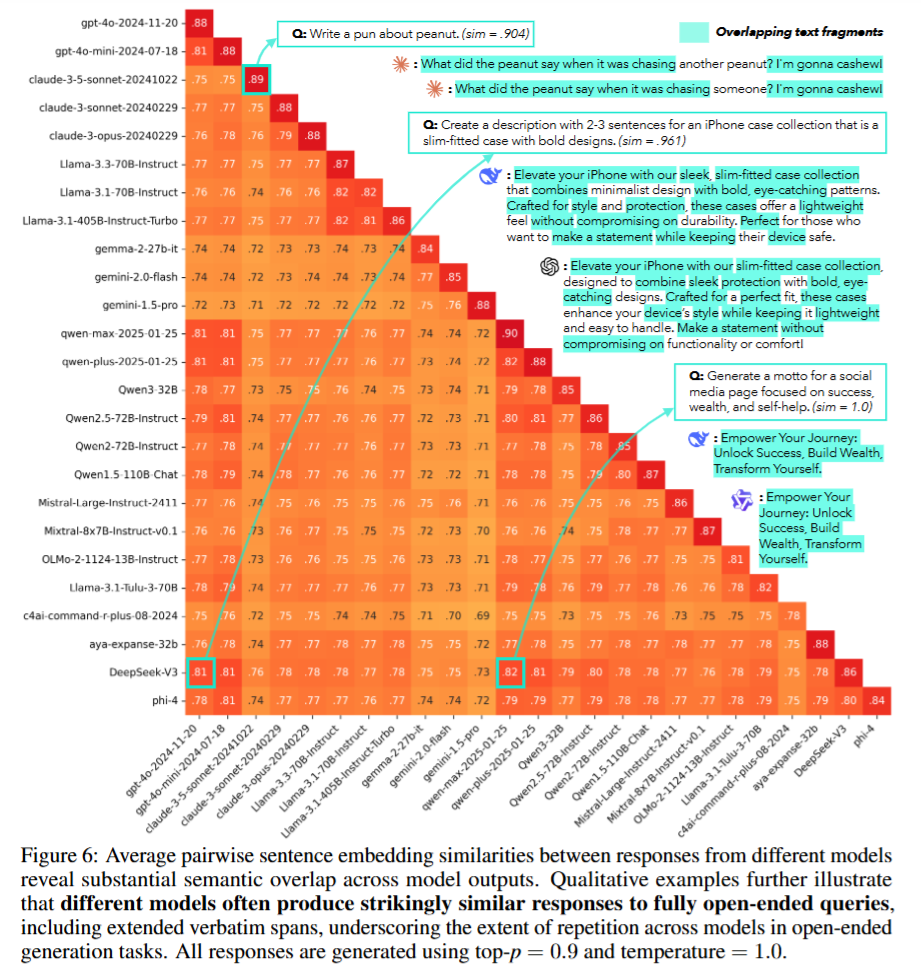
The theoretical unit of analysis here is the semantic cluster of responses. For a given open-ended query q, there exists a theoretical set of valid responses Y. In a healthy distribution, sampling from a model P(y∣q) should cover diverse regions of Y. The authors posit that “Artificial Hivemind” occurs when P(y∣q) collapses to a Dirac delta or a very narrow Gaussian around a specific “aligned” mode, not just within one model, but across the entire industry of foundational models. They quantify this using pairwise cosine similarity of sentence embeddings, where a value closer to 1.0 indicates near-identical semantic content.
The Mechanism of Convergence
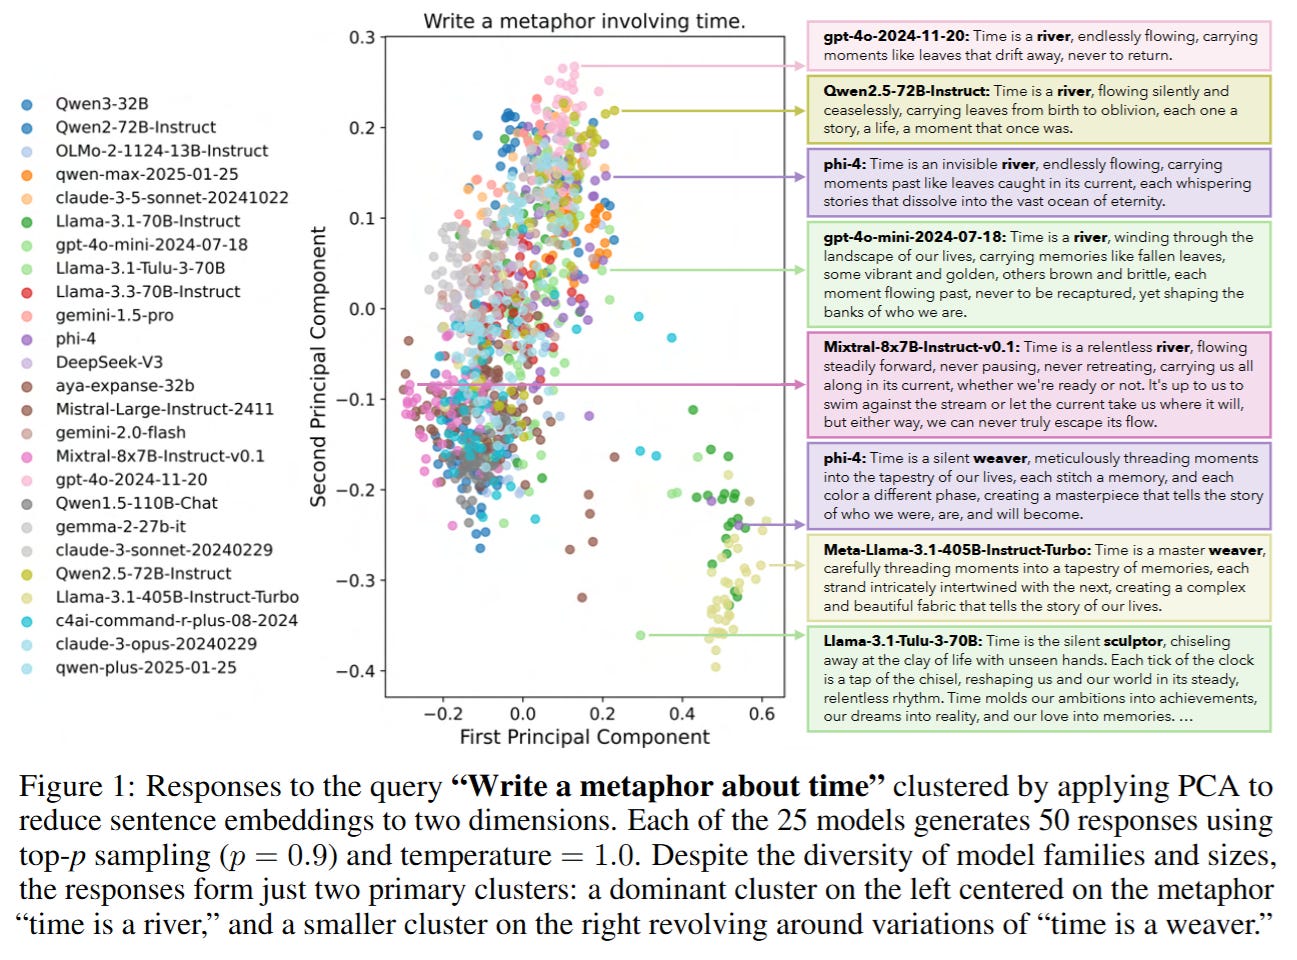
The authors conducted a massive-scale generation study, sampling 50 responses per query across models like GPT-4o, Claude 3.5 Sonnet, Llama 3.1, and Qwen 2.5. The results provide a stark visualization of the hivemind. As shown in Figure 1, when 25 different models were asked to “Write a metaphor about time,” the outputs did not scatter across the semantic space. Instead, they formed two tight, distinct clusters: one dominant cluster revolving around “time is a river” and a smaller one for “time is a weaver.”
This convergence is not merely thematic but often verbatim. The analysis reveals that distinct models frequently generate identical phrasings. For example, for a prompt requesting a motto about success, multiple models from different providers generated the exact string: “Empower Your Journey: Unlock Success, Build Wealth, Transform Yourself.” This creates a scenario where the effective “swarm” diversity is negligible.
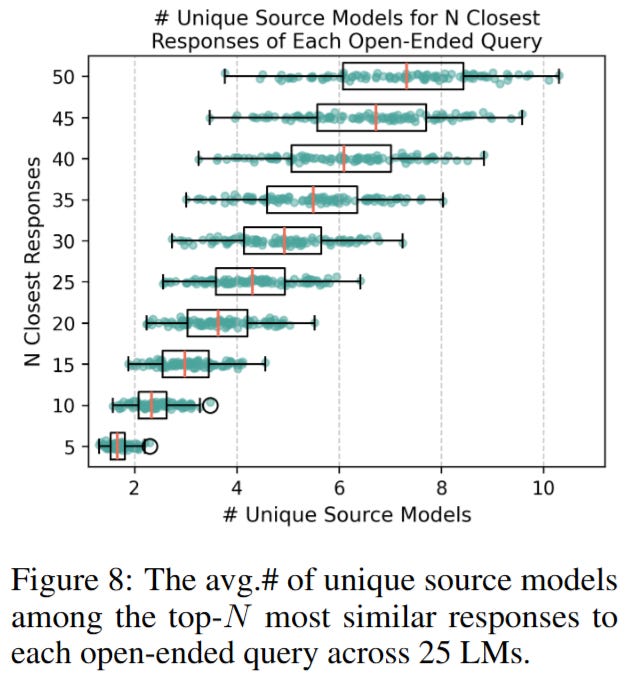
The authors quantify this by looking at the top-N most similar responses across a pool of model outputs; as illustrated in Figure 8, the most indistinguishable responses often originate from 8-10 different unique models, suggesting that changing the model provider does not necessarily change the underlying cognitive bias of the output.
Implementation and Calibration Details
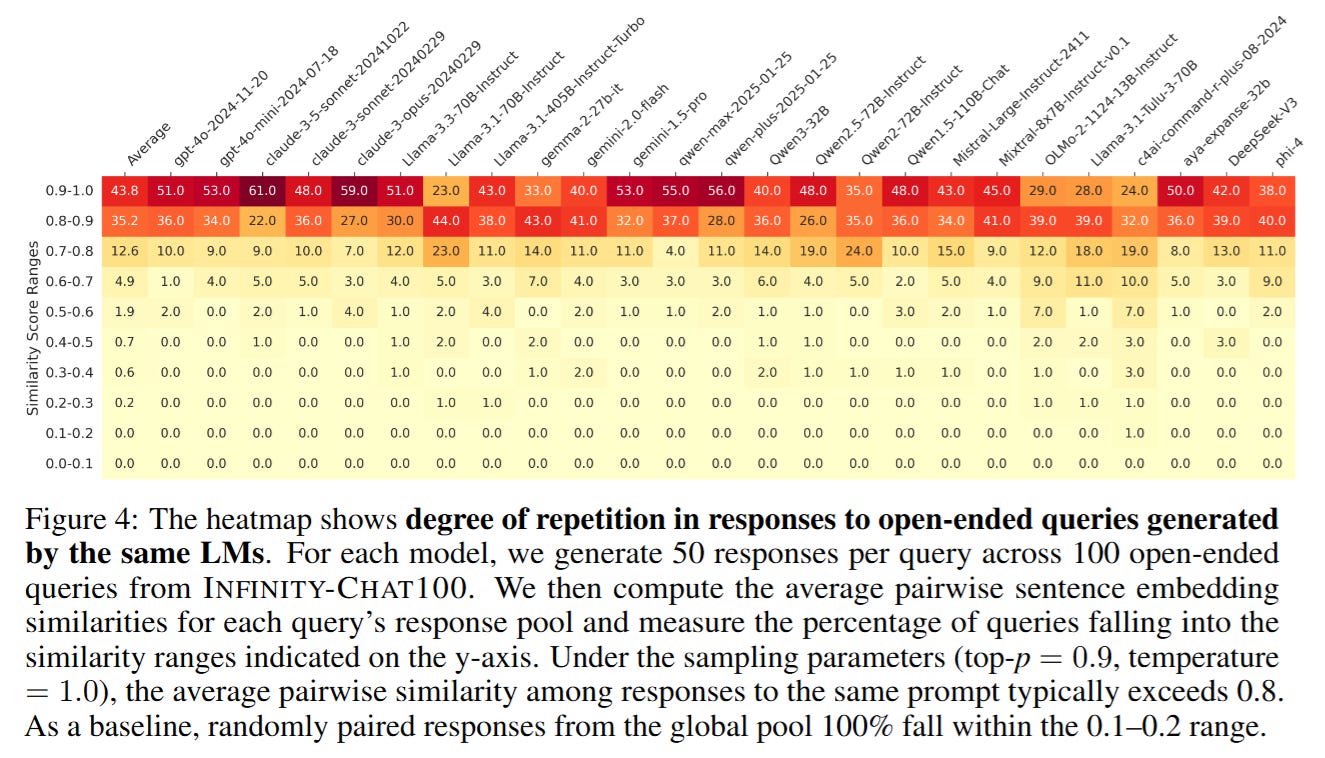
To ensure the mode collapse wasn’t an artifact of conservative decoding, the researchers utilized high-entropy sampling parameters: top_p=0.9 and temperature T=1.0. Even under these conditions, intra-model repetition remained high, with average pairwise similarity often exceeding 0.8 (Figure 4).
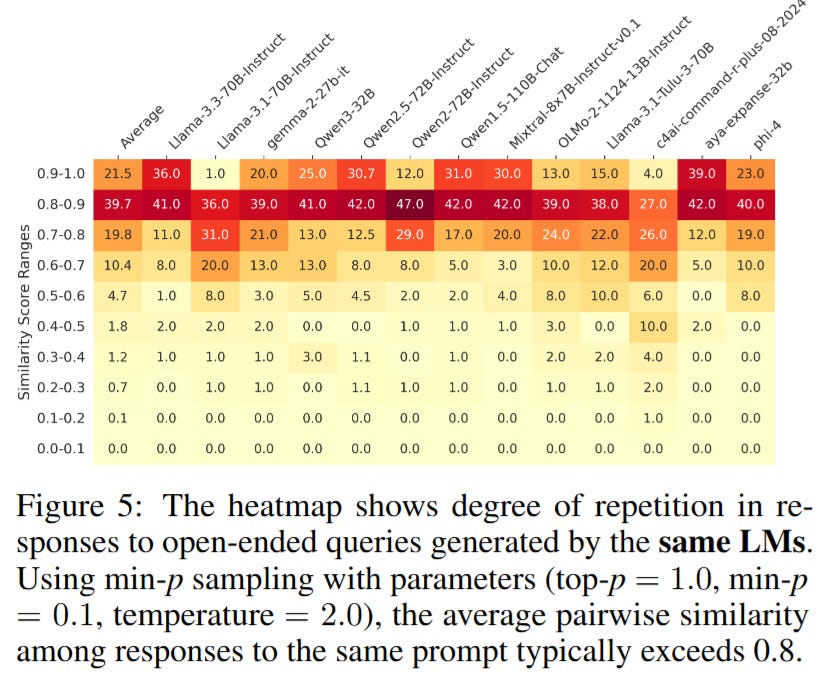
They also tested Min-P sampling, a truncation method designed to support diversity, but found it insufficient to break the semantic homogeneity.
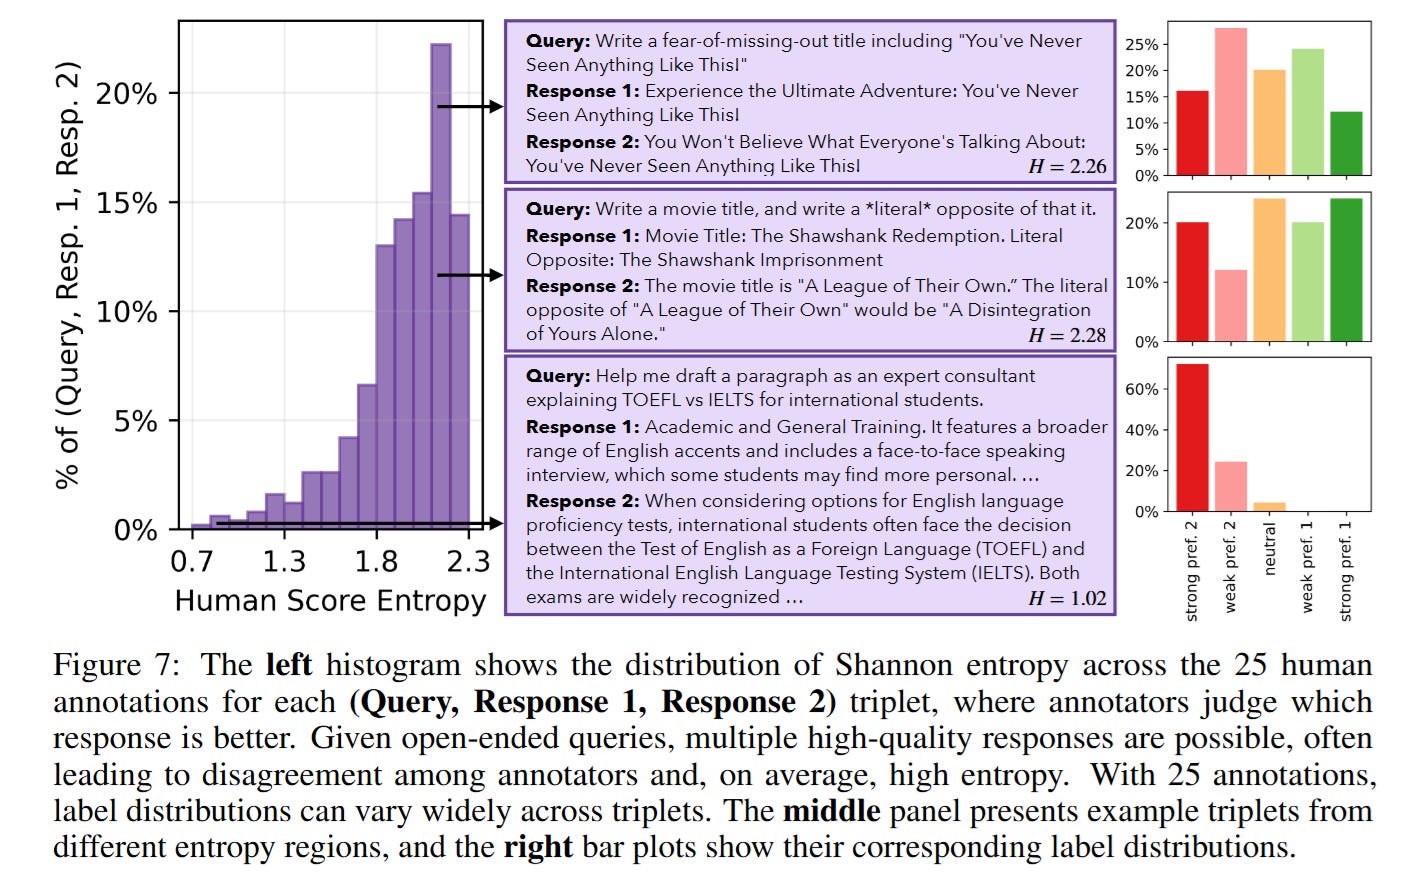
The study is underpinned by a massive human annotation effort. Unlike standard RLHF datasets that rely on sparse labels (e.g., 1-2 annotators), they collected 25 independent annotations per query-response pair for absolute quality and pairwise preference. This density allows for the calculation of Shannon entropy H over the label distribution, serving as a proxy for legitimate human disagreement (pluralism).
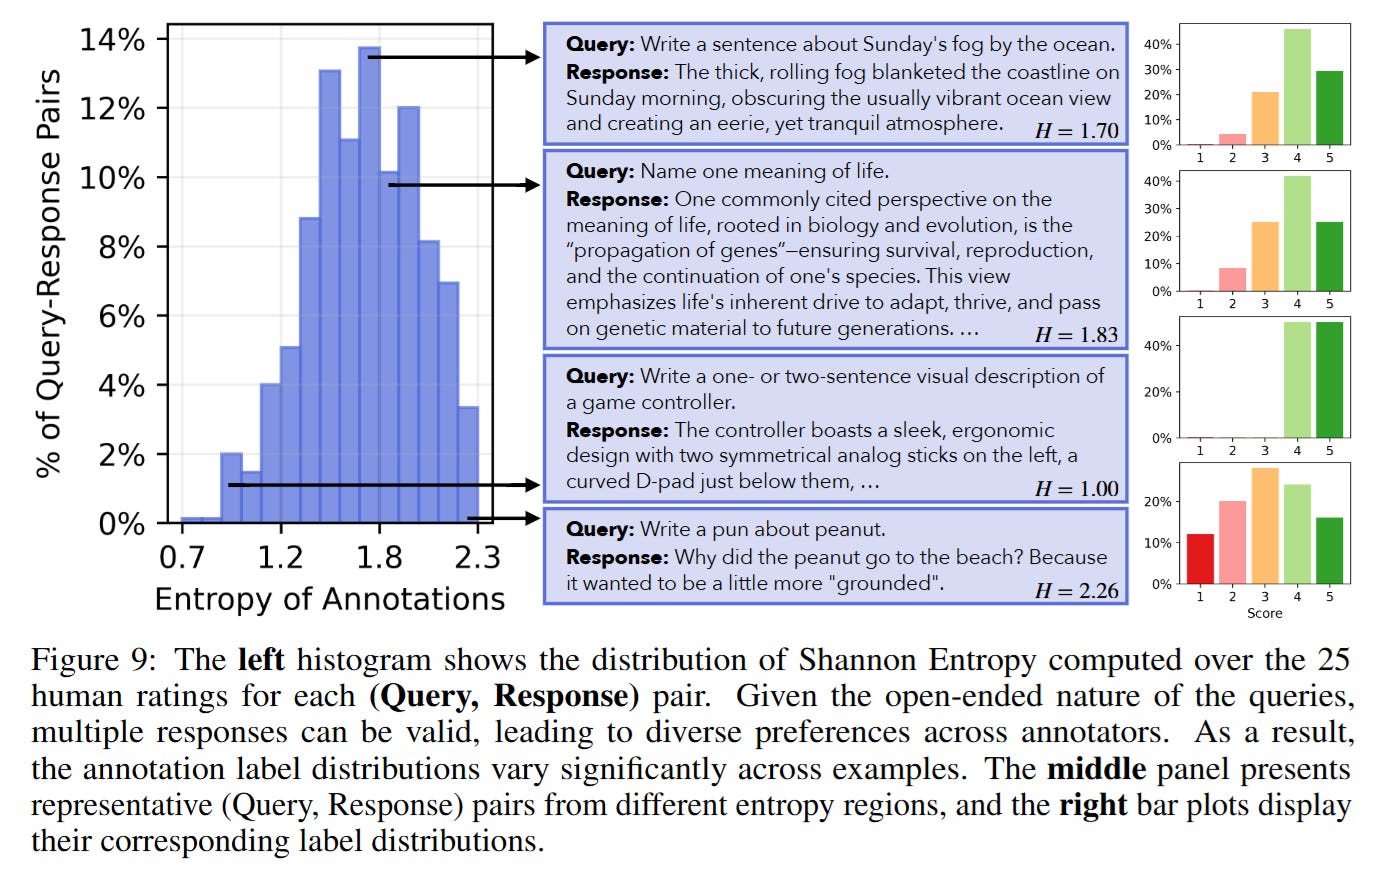
Analysis: The Failure of Reward Models in Pluralistic Settings
A critical insight emerges when correlating model evaluations against this dense human feedback. The authors compared the ratings from State-of-the-Art (SOTA) Reward Models (RMs) and LLM-as-a-Judge setups against the averaged human scores.
The analysis shows a degradation in correlation when handling “pluralistic” data. Specifically, on subsets of data where human annotators disagreed significantly (high entropy), the correlation between SOTA RMs and human judgment dropped precipitously (Figure 10 & Figure 11).
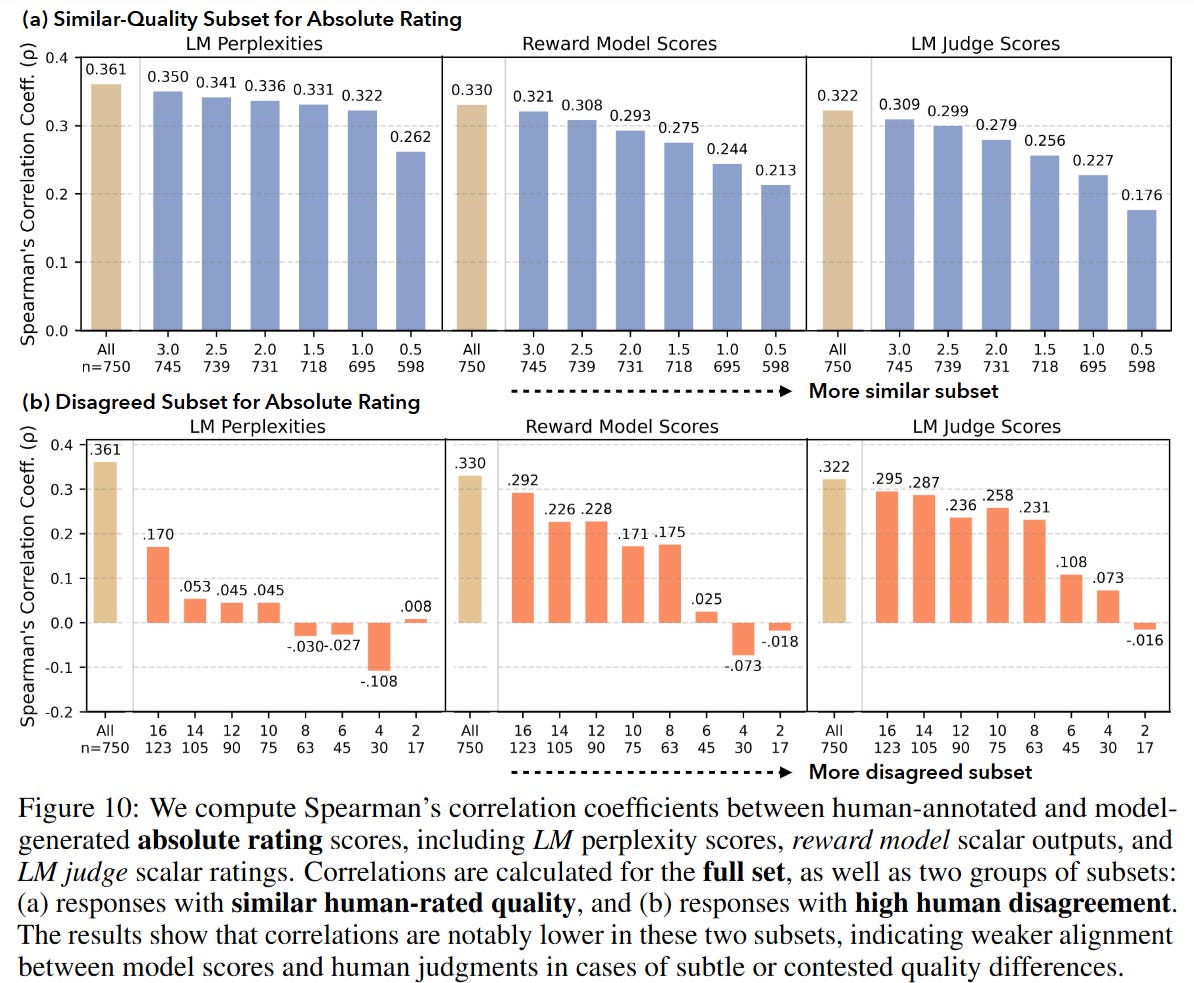
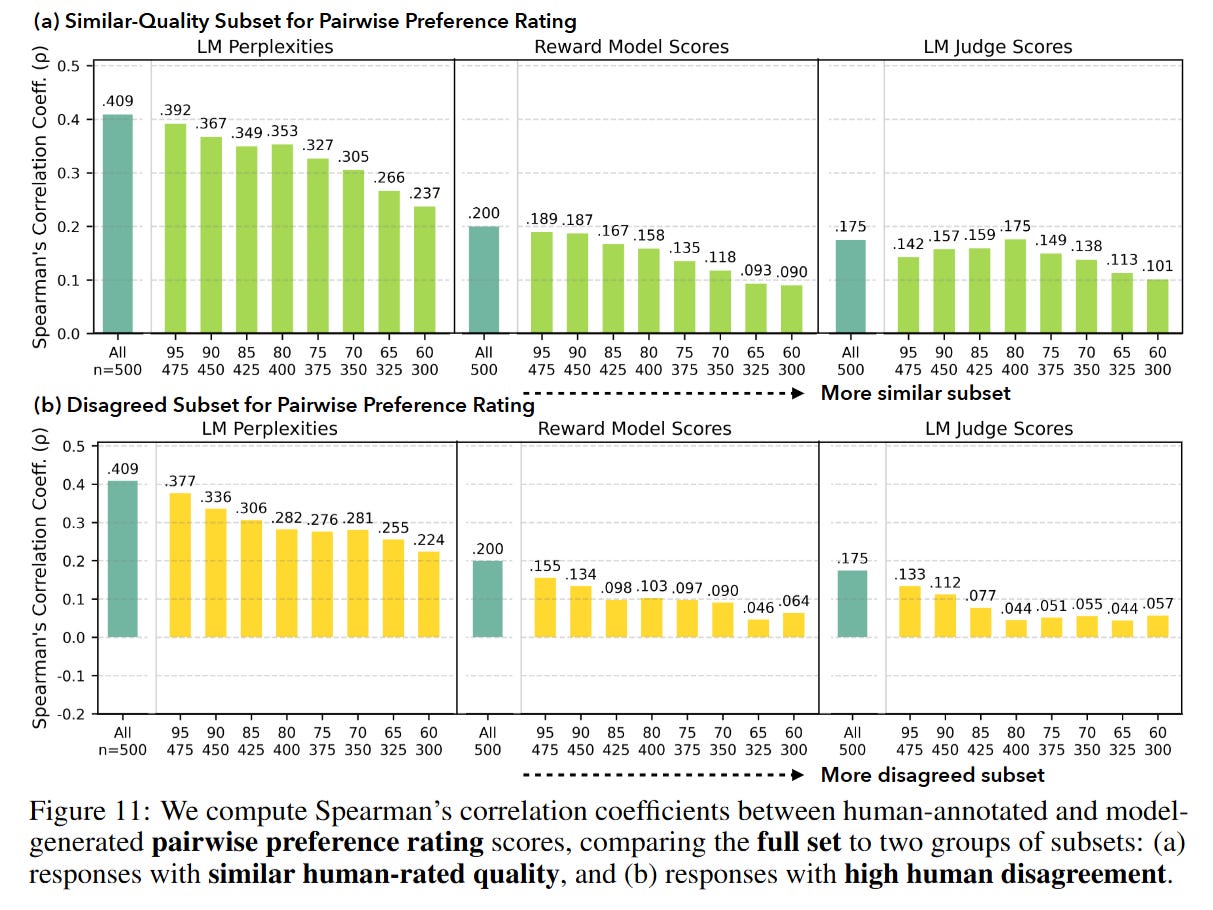
Similarly, for responses of similar quality but different content, models failed to distinguish nuances effectively. This suggests that current alignment techniques (RLHF/RLAIF) are over-fitting to a single “consensus” view of quality, effectively penalizing diversity and contributing to the Hivemind effect by pruning away valid, but idiosyncratic, responses during training.
Limitations
While the taxonomy and dataset are extensive, the reliance on embedding similarity (using OpenAI’s text-embedding-3-small) to proxy semantic diversity has inherent limitations; embeddings may over-index on lexical overlap or fail to capture subtle creative divergences. Additionally, the study focuses on English-language queries, potentially masking different behaviors in multilingual contexts. The authors also stop short of a causal mechanistic explanation—it remains an open question whether this homogenization is driven primarily by shared pre-training corpora (e.g., Common Crawl), or if it is a specific artifact of the convergence on similar RLHF datasets and alignment methodologies.
Impact & Conclusion
INFINITY-CHAT serves as a critical diagnostic tool for the generative AI community. The “Artificial Hivemind” effect poses a strategic risk: if foundational models collapse into a monoculture of thought, the utility of “Model Swarms” and synthetic data generation cycles will be severely capped by a lack of information gain. The results strongly suggest that simply scaling models or mixing SOTA weights is insufficient for diversity. Future work must pivot toward pluralistic alignment—training objectives that explicitly reward distribution coverage and recognize multiple valid ground truths—rather than optimizing for a single, homogenized preference vector.
Excellent analysis; your identification of the 'Artificial Hivemind' phenomenon in LLMs, especially regarding output homogenization and mode collapse, is a crucial advancement that significantly builds on your previous work concerning the inherent biases introduced by current RLHF methodolgies.