Authors: The Omnilingual MT Team, Belen Alastruey, Niyati Bafna, Andrea Caciolai, Kevin Heffernan, Artyom Kozhevnikov, Christophe Ropers, Eduardo Sánchez, Charles-Eric Saint-James, Ioannis Tsiamas, Chierh Cheng, Joe Chuang, Paul-Ambroise Duquenne, Mark Duppenthaler, Nate Ekberg, Cynthia Gao, Pere Lluís Huguet Cabot, João Maria Janeiro, Jean Maillard, Gabriel Mejia Gonzalez, Holger Schwenk, Edan Toledo, Arina Turkatenko, Albert Ventayol-Boada, Rashel Moritz, Alexandre Mourachko, Surya Parimi, Mary Williamson, Shireen Yates, David Dale, Marta R. Costa-jussà
Paper: https://ai.meta.com/research/publications/omnilingual-mt-machine-translation-for-1600-languages/
Benchmark: https://huggingface.co/spaces/facebook/bouquet
TL;DR
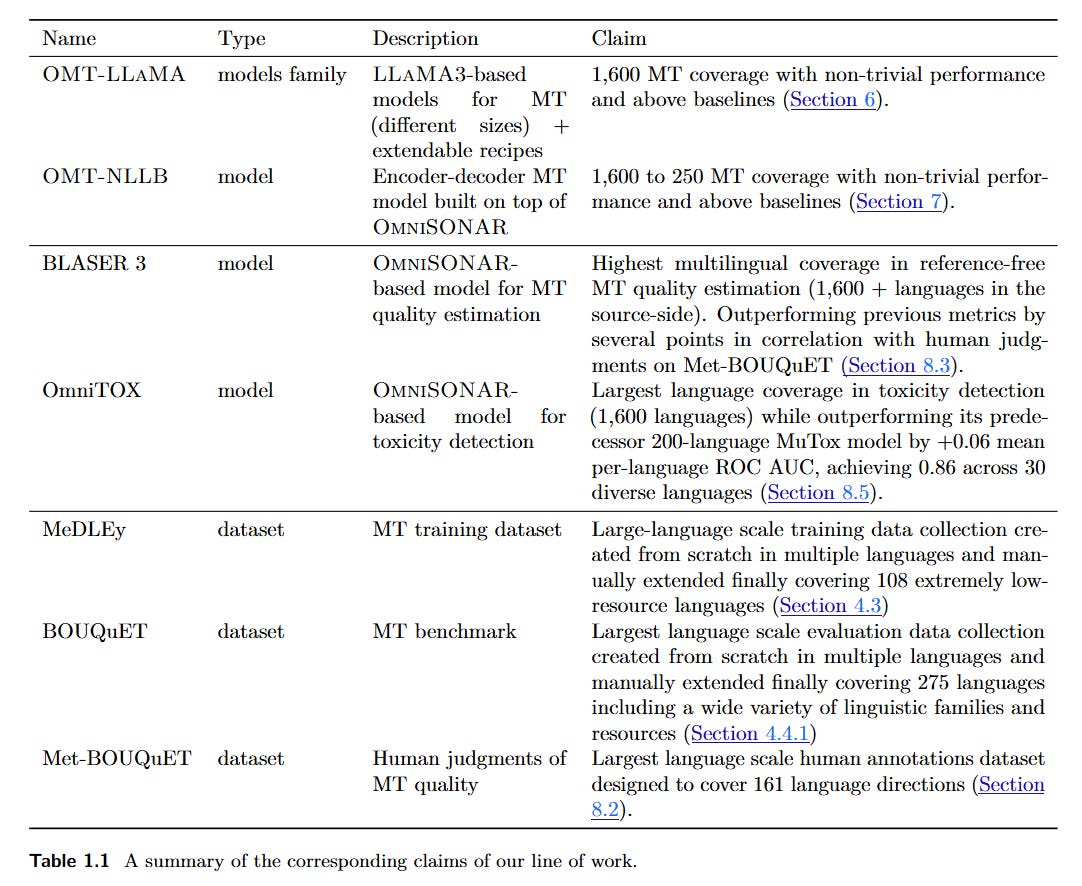
WHAT was done? Researchers at FAIR (Meta) have introduced Omnilingual Machine Translation (OMT), a comprehensive suite of models, datasets, and evaluation metrics that extends machine translation support to over 1,600 languages. They propose two distinct architectural pathways: a decoder-only lineage (OMT-LLaMA) built on LLaMA 3, and a 3B-parameter encoder-decoder model (OMT-NLLB) derived from the OmniSONAR cross-lingual embedding space. To support this scale, the team additionally developed the ¬y seed dataset, the BOUQuET and Met-BOUQuET evaluation frameworks, and the BLASER 3 reference-free quality estimation metric.
WHY it matters? This work shatters the operational ~200-language ceiling that has defined the frontier of massively multilingual machine translation for the past several years. More strategically, it isolates and addresses the “generation bottleneck”—the phenomenon where large models can interpret undersupported languages via cross-lingual transfer but fail to generate coherent text in them. By demonstrating that specialized 1B to 8B parameter models can match or exceed the translation performance of 70B parameter foundational models, this research establishes a Pareto-efficient blueprint for global linguistic inclusion.
Executive summary: For practitioners deploying large language models globally, this paper demonstrates that sheer parameter scaling is an inefficient mechanism for capturing the long tail of human languages. Instead, targeted interventions—such as massive vocabulary expansion, cross-lingual sentence embedding alignment, and structured data generation across grammatical paradigms—yield superior translation fidelity at a fraction of the inference cost. The introduction of BLASER 3 also provides a scalable, automated alternative to expensive human quality estimation across thousands of dialects and scripts.
Details
The Generation Bottleneck in Massively Multilingual Translation
The evolution of massively multilingual machine translation has recently plateaued. Foundational systems successfully pushed the boundary to approximately 200 languages, establishing robust pipelines and evaluation standards that benefit high-resource and mid-resource demographics.
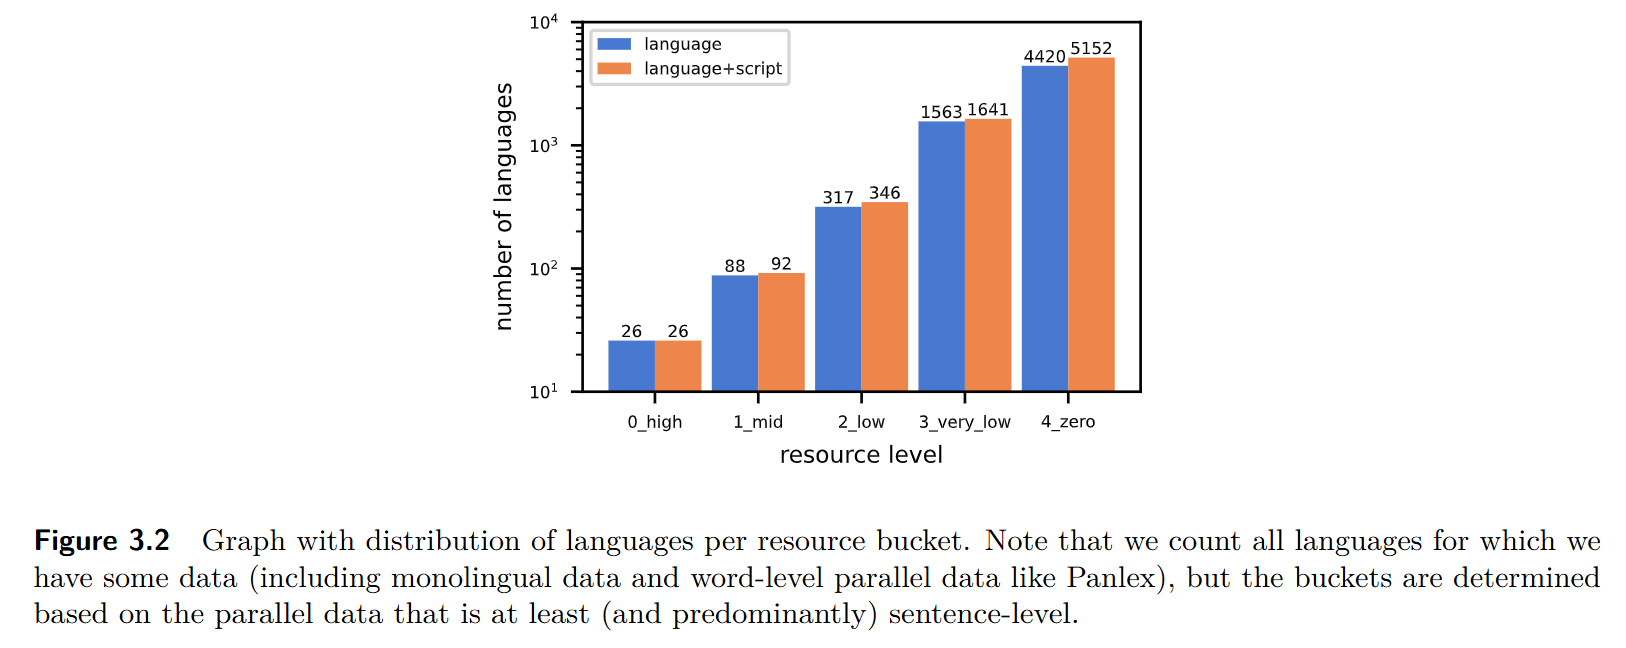
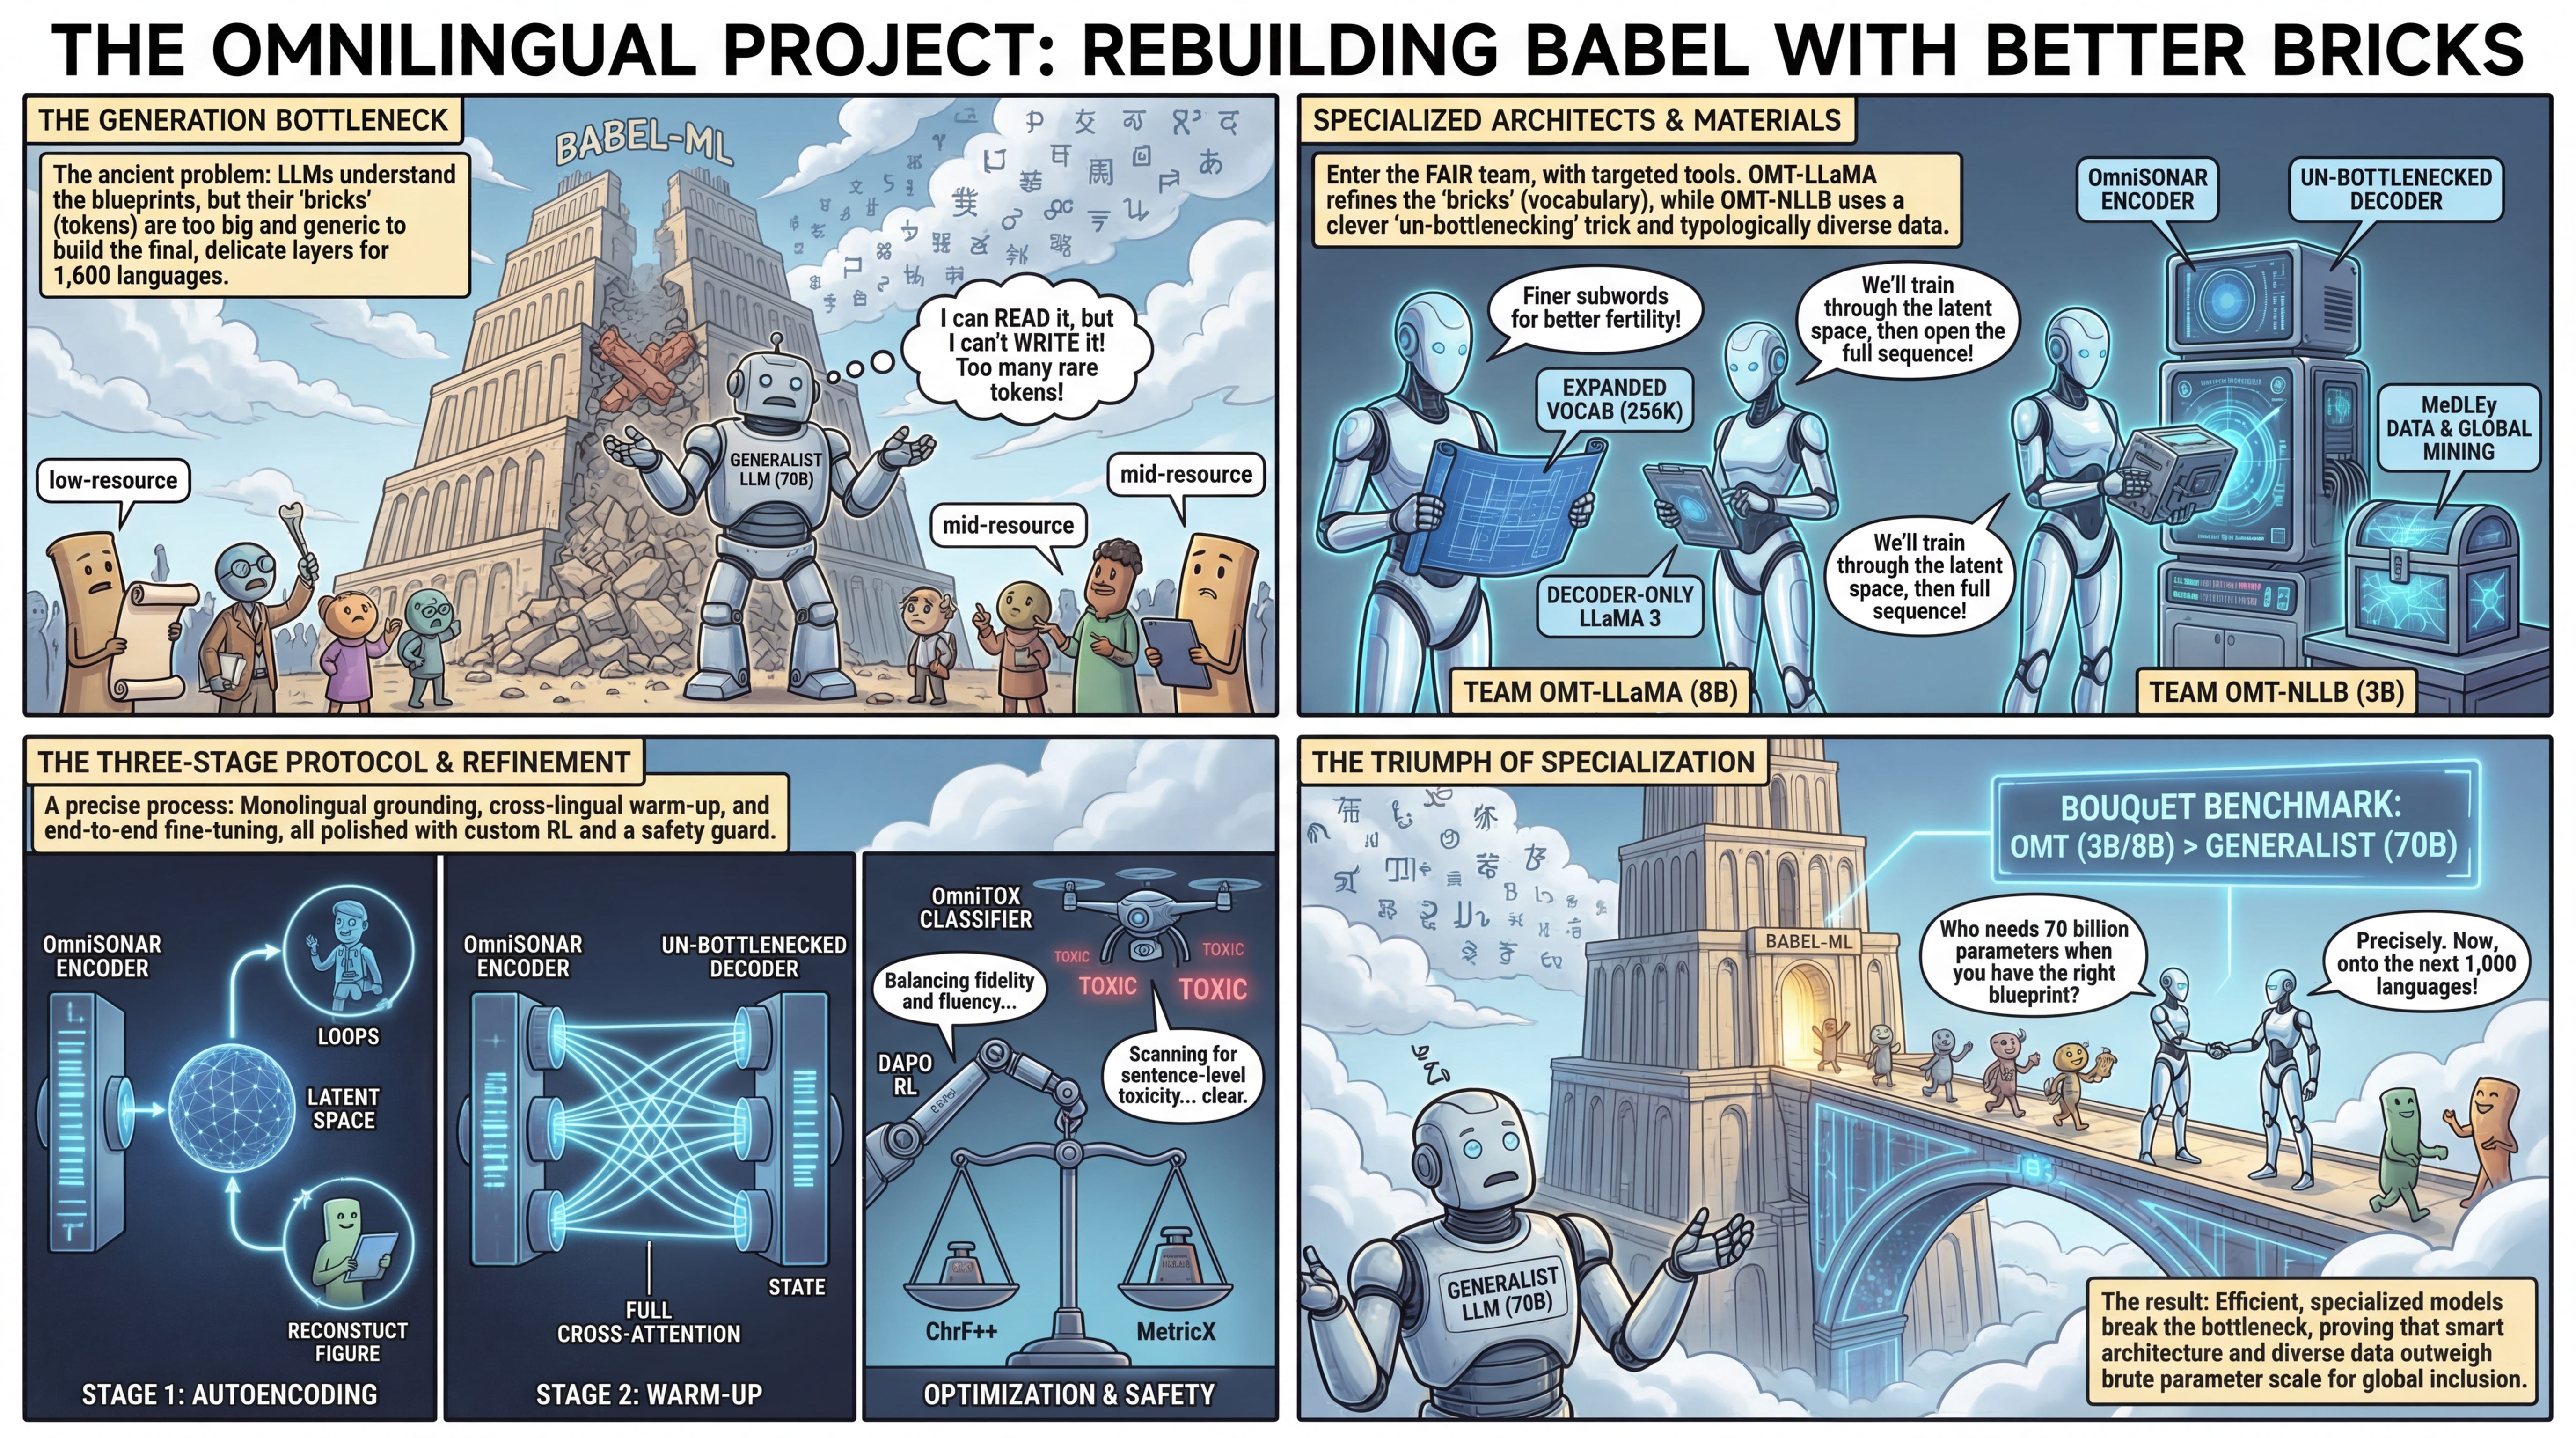
However, subsequent reliance on generic, massively scaled language models has exposed a fundamental asymmetry in multilingual representation: the generation bottleneck. While cross-lingual transfer enables large models to passively comprehend long-tail and marginalized languages, these models structurally fail to generate them with any reliable fidelity. When evaluated on underserved languages, outputs often degrade into hallucinations, heavy code-switching, or literal, incoherent translations. This delta between comprehension and generation leaves the vast majority of the world’s 7,000 languages outside the practical reach of current AI systems.
Representational Foundations: Cross-Lingual Spaces and Tokenization
To break past this barrier, the authors anchor their approach in first principles regarding how discrete text is mapped into continuous spaces. The core theoretical substrate for their encoder-decoder architecture relies on OmniSONAR, a massively multilingual joint embedding space. In this manifold, semantically equivalent sentences from entirely different languages are projected into the same dense vector representation e∈Rds, where ds is the dimensionality of the embedding space. This language-agnostic bottleneck theoretically allows a decoder to generate text in a target language using representations learned from high-resource languages. Conversely, for their decoder-only architecture, the primary substrate intervention is vocabulary extension. Relying on the standard LLaMA 3 Byte-Pair Encoding (BPE), the authors sequentially merge the most frequently occurring consecutive pairs of tokens across a newly curated corpus of thousands of languages. This expands the vocabulary from 128K to 256K tokens, drastically lowering the “fertility” (the number of subword tokens required to represent a given semantic concept) for languages with non-Latin scripts. Lower fertility ensures that the model expends less of its capacity reconstructing basic morphology and more capacity modeling complex syntax.
Two Pathways to Omnilinguality: The OMT Mechanisms
The system operationalizes these representations through two parallel modeling strategies. To understand the OMT-NLLB encoder-decoder mechanism, consider a single Swahili sentence fed into the system.
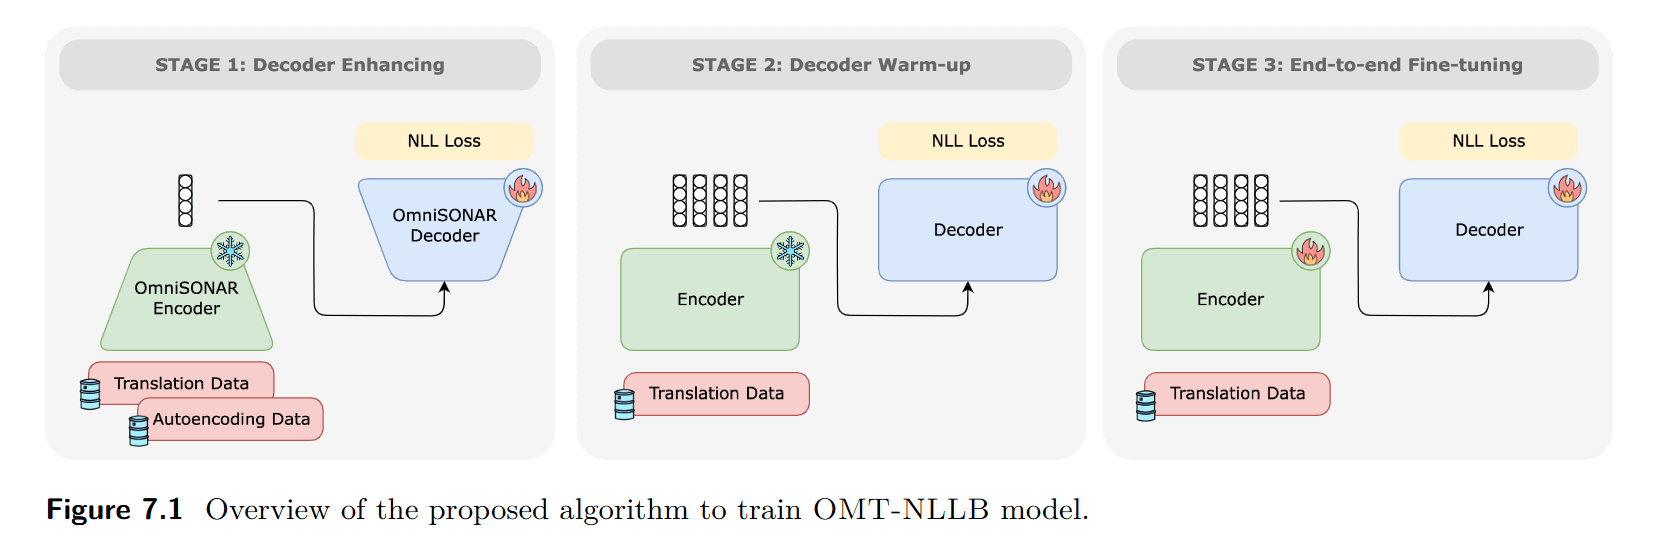
As shown in Figure 7.1, the sentence first passes through a frozen OmniSONAR encoder, which compresses the entire sequence into a single, pooled semantic vector. In the first training stage, the decoder is trained to reconstruct the Swahili sentence from this pooled vector using an auto-encoding objective on non-parallel monolingual data. While this forces the decoder to learn the grammar of Swahili, the single-vector bottleneck restricts fine-grained information transfer. In the second stage, the algorithm structurally removes this bottleneck, wiring the frozen encoder directly to the decoder via standard token-level cross-attention. The decoder undergoes a warm-up phase to adapt to reading a full sequence of hidden states rather than a single vector. Finally, in the third stage, the entire model is unfrozen and fine-tuned end-to-end on parallel bitext, allowing the Swahili input to map directly to an English target with full token-level granularity.
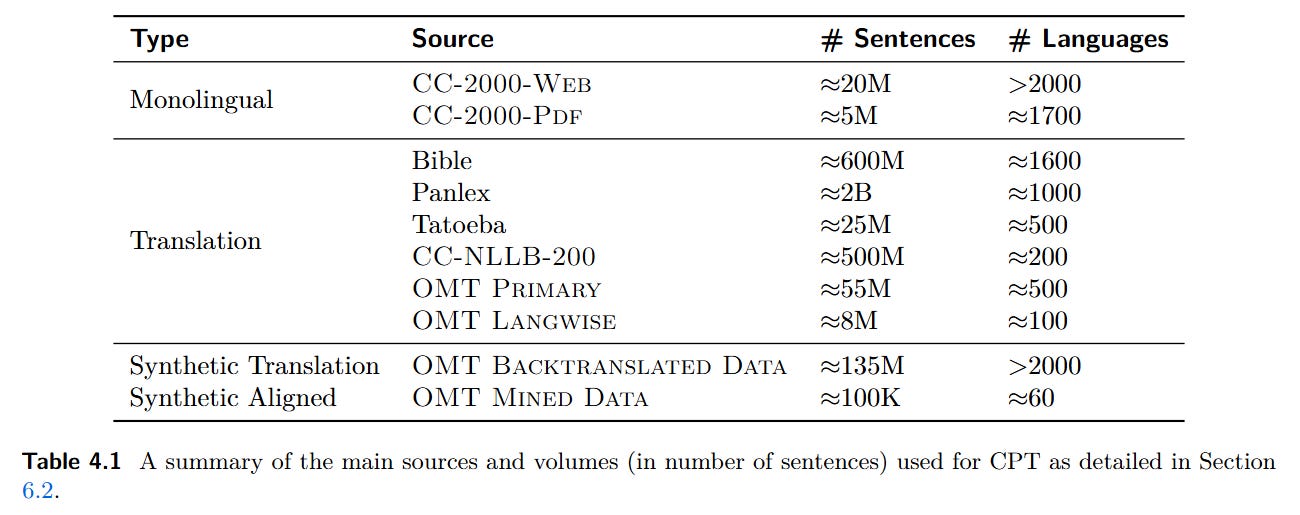
The decoder-only OMT-LLaMA pathway takes a different approach. After vocabulary expansion, the model undergoes continual pretraining (CPT) on a mixture of monolingual language modeling and parallel translation tasks. It is then subjected to Supervised Fine-Tuning (SFT) and Reinforcement Learning (RL).
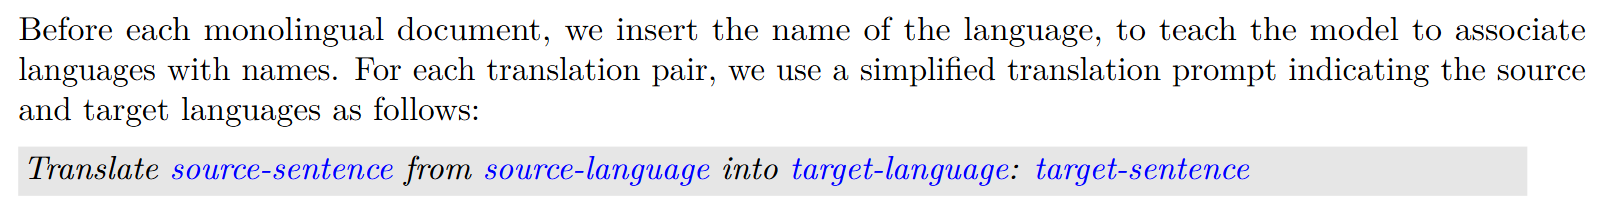
During inference, if the model encounters a particularly obscure language pair, it utilizes Retrieval-Augmented Translation, querying a Lance-format database to inject contextually relevant parallel text chunks into the prompt as few-shot examples, steering the generation toward the correct dialect and register.
Engineering Stability at a Thousand-Language Scale
Executing this pipeline requires rigorous optimization and hardware coordination. The OMT-LLaMA continual pretraining was distributed across a cluster of 256 NVIDIA A100 GPUs, running for 50,000 steps. The models were optimized using AdamW with a learning rate of η=5×10⁻⁵, β1=0.9, β2=0.95, and a weight decay of λ=0.1. The maximum sequence length was strictly capped at 8,192 tokens. For the RL phase, the authors bypassed standard PPO in favor of Decoupled Clip and Dynamic Sampling Policy Optimization (DAPO) with a group size of N=64, utilizing a reward function that evenly blended ChrF++ and MetricX scores to prevent the model from gaming a single lexical metric.
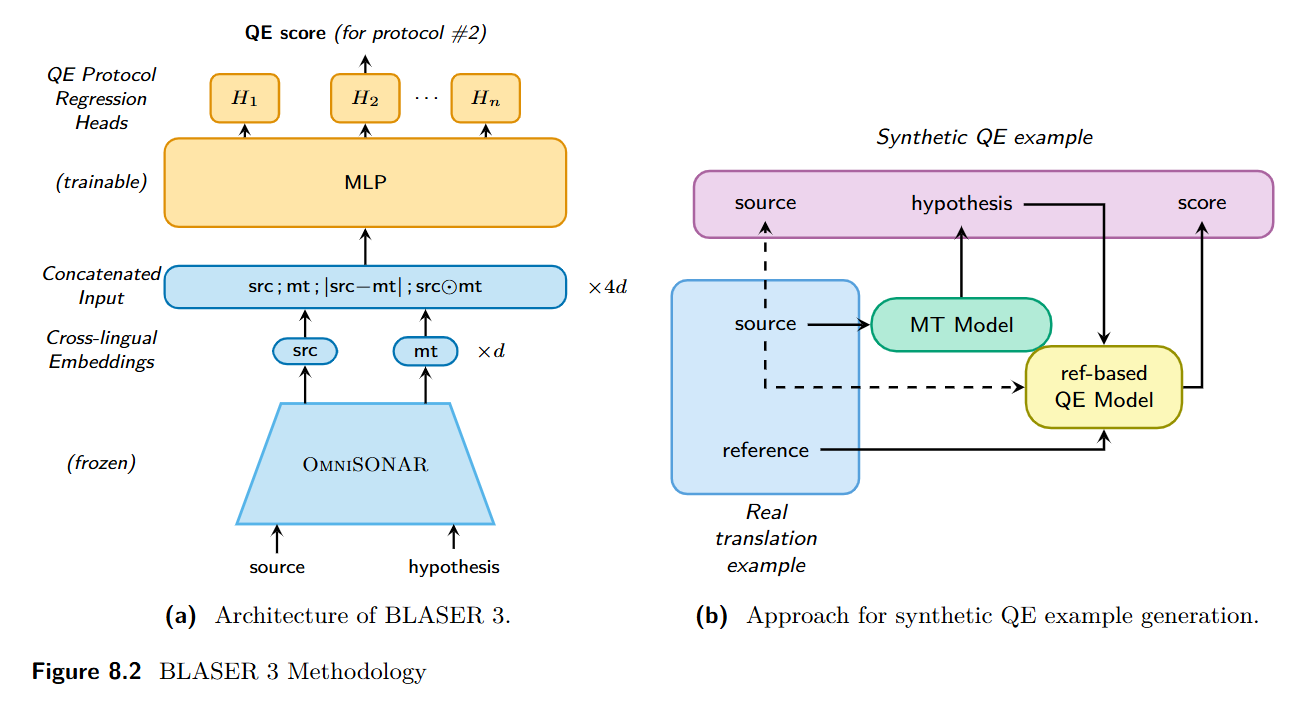
To evaluate these massive models without relying on human annotators for 1,600 languages, the researchers developed BLASER 3, a reference-free quality estimation metric. This model computes an MSE loss Lmse=∣∣s(i)−ŝ(i)∣∣2, where s(i) is the ground-truth human annotation score and ŝ(i) is the model’s prediction. The prediction is derived by taking the OmniSONAR embeddings of the source and target texts, computing their element-wise difference and multiplication, concatenating these into a single vector, and passing it through a two-layer Multi-Layer Perceptron.
Analysis: Decoupling Scale from Linguistic Competence
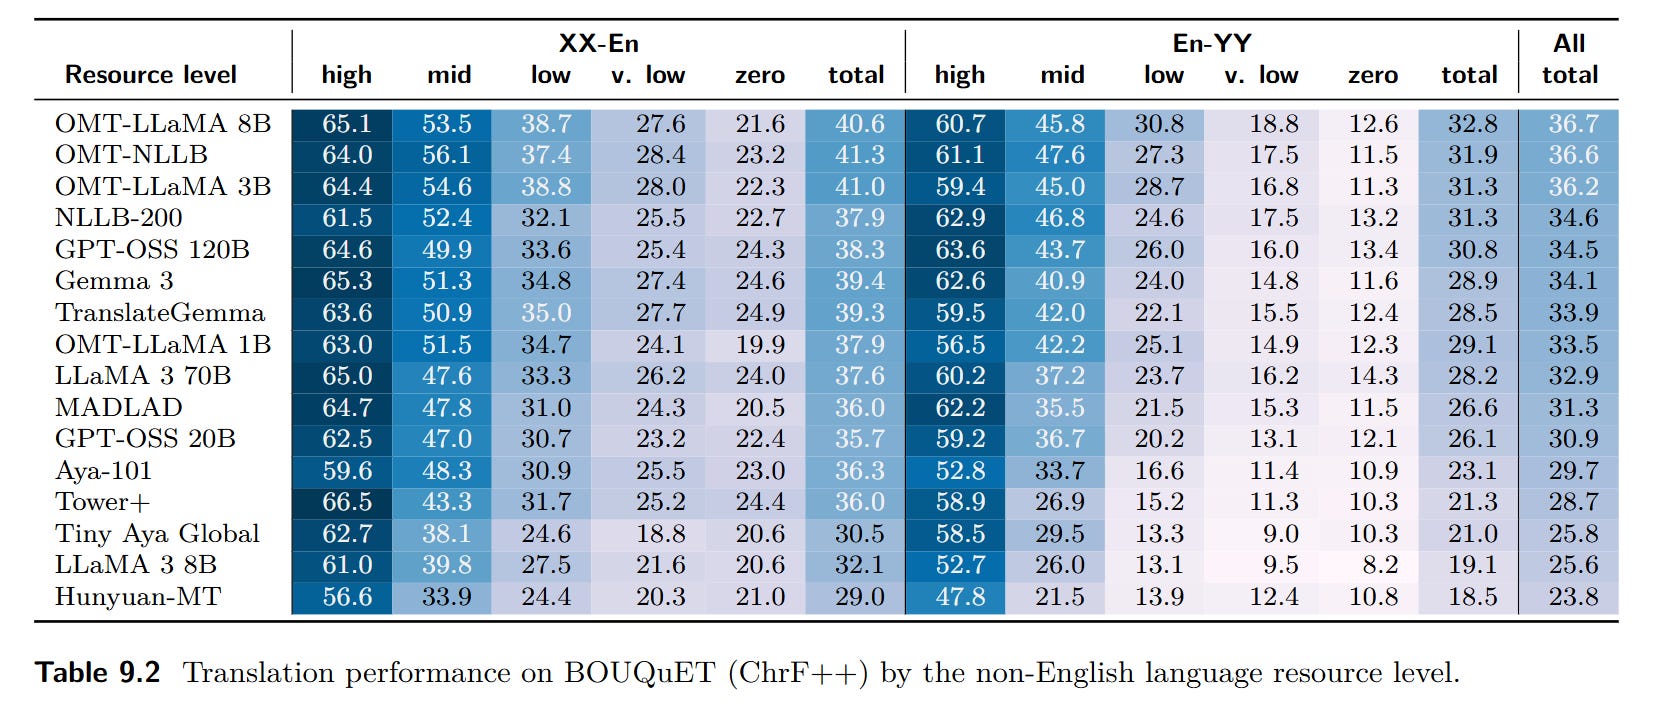
The empirical validation demonstrates that targeted architectural and data interventions overshadow raw parameter count in multilingual translation. As detailed in Table 9.2, the 8B, 3B, and even 1B parameter OMT-LLaMA models consistently match or outperform the LLaMA 3 70B baseline on the BOUQuET evaluation dataset, proving that scale alone does not solve the generation bottleneck.
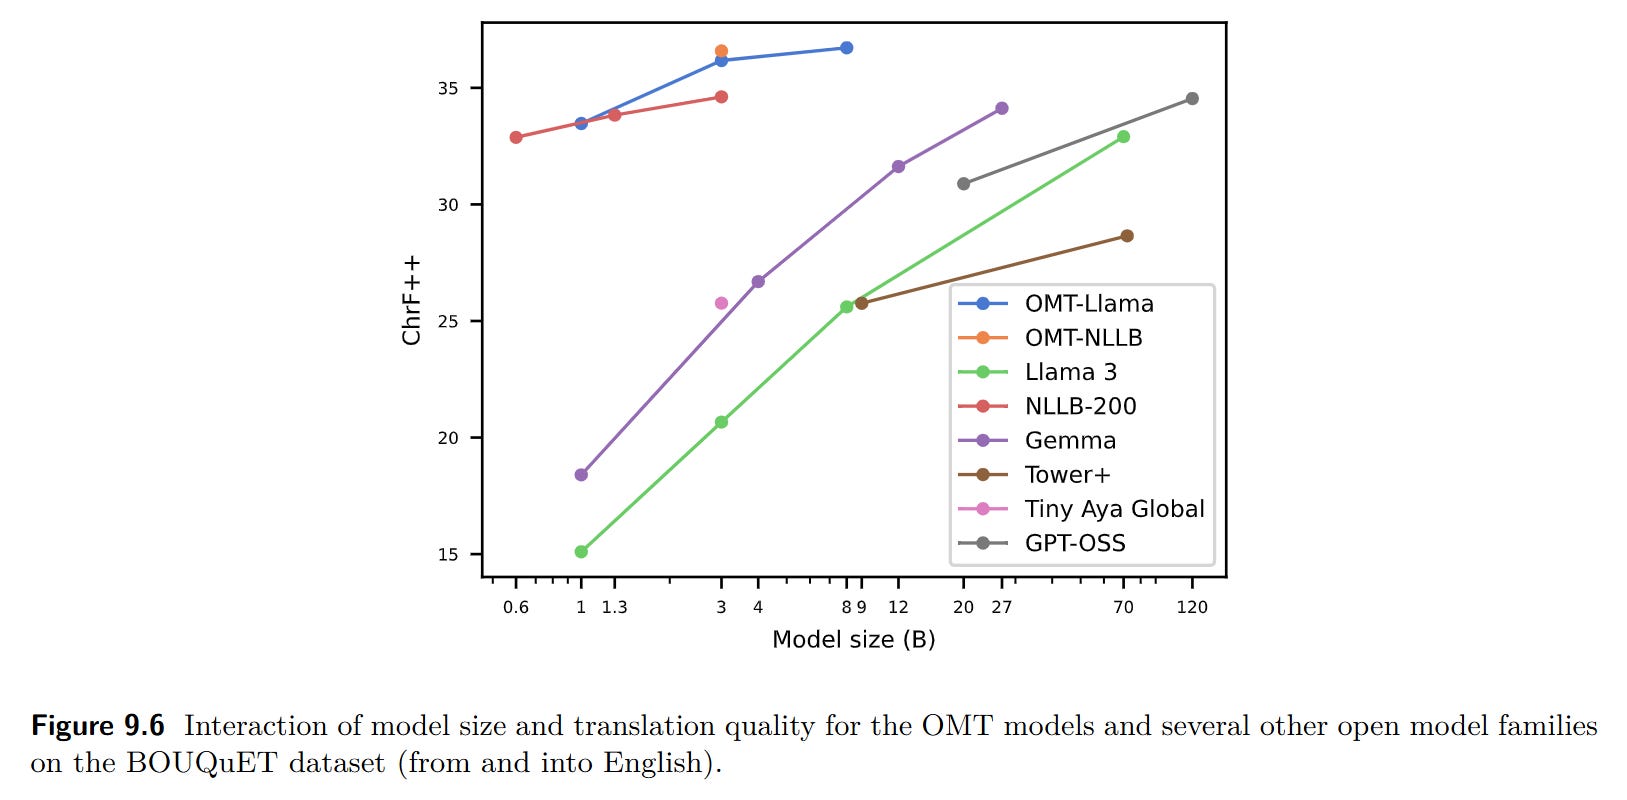
Furthermore, Figure 9.6 visually confirms this size-performance inversion across multiple model families.
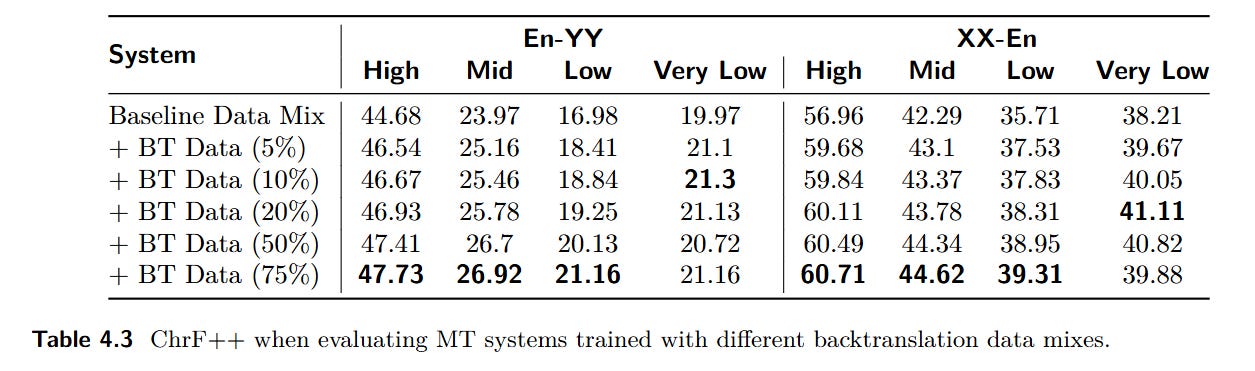
The ablation studies on data synthesis offer deep insights into optimal training mixtures. When mixing synthetic backtranslated data with natural bitext, the authors found that extreme ratios harmed performance. According to Table 4.3, maintaining a ratio of roughly 1:9 (5% to 10% backtranslated data) yielded optimal ChrF++ scores for low-resource languages, suggesting that while synthetic data helps bridge vocabulary gaps, over-reliance rapidly induces model collapse and degrades morphological coherence.
Trajectories in Linguistic Scaling
This research sits at the convergence of several recent initiatives aimed at linguistic inclusivity. It directly builds upon the foundations laid by the NLLB team, expanding their 200-language scope. It also mirrors early exploratory efforts like Google’s Massively Multilingual Translation project, which probed the feasibility of a 1,000-language limit but lacked sustained data pipelines. In terms of data curation, the introduction of the MeDLEy dataset shares philosophical DNA with recent parallel corpora efforts like SMOL, focusing on grammatically diverse, human-curated seeds rather than scraped noise. On the modeling front, the decision to interleave translation tasks with general instruction tuning draws heavily from specialized LLM architectures like TowerLLM, proving that cross-lingual capabilities can be preserved and amplified without destroying the underlying model’s reasoning behaviors.
Evaluating the Evaluators: The Limits of Met-BOUQuET
While the scope of the evaluation is unprecedented, the methodology carries inherent limitations. The toxicity classifier, OmniTOX, is primarily trained on English and Spanish annotations, which inherently risks projecting Western definitions of toxicity and profanity onto a global array of cultures. Furthermore, while automatic metrics like BLASER 3 and MetricX correlate well with human judgment on sentence-level semantics, the authors’ manual analysis reveals that these automated systems still fail to penalize catastrophic register shifts or paragraph-level continuity errors. A model might translate a highly formal instructional text using overly casual street slang in the target language; a human evaluator would flag this immediately, whereas the vector-based metrics frequently score the semantic overlap as a success.
Strategic Implications for Foundation Models
The Omnilingual MT initiative serves as a definitive proof of concept that solving the world’s language barriers is an architectural and data-curation problem, not merely a compute-scaling problem. By achieving state-of-the-art translation across 1,600 languages with a 3B parameter model, this work subverts the prevailing industry narrative that ever-larger foundational models will naturally subsume all niche tasks. For research organizations, the strategic takeaway is clear: embedding spaces like OmniSONAR and highly structured, grammatically diverse seed datasets provide a more efficient, Pareto-optimal route to global deployment than brute-force pretraining.